Field
A Mining Group Consolidated 500,000 Product Records
Nathalie · 2026-01-12 · Updated 2026-10-23 · 6 min read
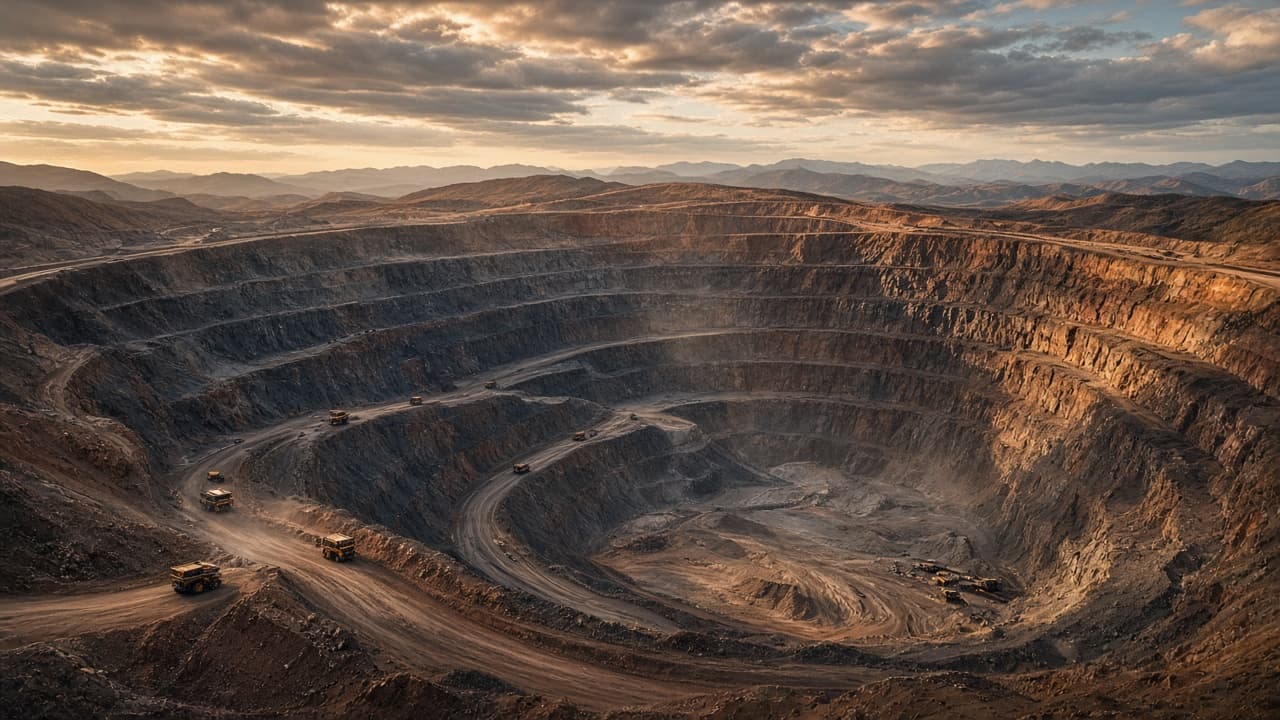
The mining group got one product catalogue by running the data model, the platform and the enrichment as one job. It operates in 12 or more regions. Decades of growth and acquisitions left more than 500,000 product records across ERP instances, procurement platforms and local spreadsheets, in different languages and different classification logic. PIMvendors designed a UNSPSC model, ran the PIM/MDM selection, and put industrial AI on the cleansing, with a person checking the output.
The situation
The same hydraulic pump could appear as five descriptions, in three languages, under two UNSPSC codes, with nothing linking them. For a group that spends billions a year on MRO materials, that split is a cost problem, a safety problem and a downtime problem.
Maintenance crews could not find the right parts. Procurement could not see duplicate spend. Strategic sourcing could not consolidate suppliers. Regional teams had learned to work around the catalogue. Earlier cleanups with generic AI and bulk reclassification had failed. Crusher liners, conveyor belt segments and specialised filtration media do not show up in consumer product databases, so generic enrichment returned output the crews could not use.
The group asked PIMvendors to deliver three workstreams: a unified product data model, a PIM/MDM platform, and AI cleansing and enrichment built for industrial MRO.
Workstream 1: Product data model
No two regions described a product the same way. Some sites kept technical specifications. Others relied on free text typed by warehouse operators. There was no shared taxonomy, no agreed attribute set, and no definition of a complete record.
PIMvendors anchored the model on UNSPSC, the classification most widely used for indirect materials and MRO. Regional structures were set against that model to find gaps, conflicts and duplicates. Each category got mandatory and optional attributes, standard units, and naming rules that work in more than one language.
This was tested with procurement leads, maintenance engineers and warehouse managers in four pilot regions. The test was operational. If a technician could not find a conveyor idler roller within three clicks from the new classification and attributes, the model went back for revision.
The outcome is one UNSPSC model covering 100 percent of the group's MRO categories. Each category has an attribute template and validation rules, so quality is checked when a record is created.
Workstream 2: Platform selection
There was no central system of record. ERP master data modules handled transactions and offered no workflow, no governance and no enrichment. Data stewards kept their own golden records in Excel. A central platform had to cope with multi-region governance, several languages, and the volume of an industrial MRO catalogue.
PIMvendors ran a selection from a long list of more than 15 PIM and MDM platforms down to a shortlist of 3. The criteria were specific: UNSPSC hierarchies at this scale, onboarding from ERPs that do not match each other, a fit with the AI tools planned for the third workstream, and the group's IT architecture and security rules.
Each shortlisted vendor demoed on the client's data, from a script. Generic demo sets stayed out of the room. The panels included IT, procurement, maintenance and data governance. PIMvendors delivered an independent score and a recommendation, with total cost of ownership over five years.
The platform was selected and the implementation roadmap delivered within 10 weeks. It is specified for more than 500,000 SKUs, 12 or more regional feeds and 8 languages, with workflow for stewardship, approval routing and supplier onboarding.
Workstream 3: Cleansing and enrichment
The history was still a mess after the model and the platform were chosen. Over 40 percent of records were free text with no structured attributes. Classification accuracy across the catalogue was estimated below 60 percent. Duplicates were everywhere. General-purpose language models, tuned on consumer products, could not tell a type 3 butterfly valve from a type 5, or a ball mill liner from generic metalwork.
PIMvendors identified, evaluated and deployed AI tools built for industrial and MRO enrichment. Those tools are trained on millions of industrial product records and technical data sheets, which is the vocabulary generic models lack.
The pipeline had three stages. Classification assigned a UNSPSC code from the description, the attributes already present, and the context around the record. Attribute extraction pulled material, dimensions, operating specifications and OEM part numbers out of free text and into the model. Duplicate detection used probabilistic matching across regions and flagged clusters for consolidation.
A steward reviewed every AI suggestion, in batches: accept, correct or reject. That loop improved the model and left the group in control of its master data.
Free-text records fell from over 40 percent to below 10 percent. Classification accuracy rose above 95 percent. Duplicate clusters were consolidated, and the active catalogue shrank by an estimated 15 to 20 percent. New product onboarding, previously weeks of manual entry and cross-checks, now takes days.
The combined impact
The model supplies the structure. The platform supplies the governance. The AI supplies the speed on hundreds of thousands of records. All 12 or more regions now work from one catalogue. Procurement can run spend analysis, and can consolidate suppliers and negotiate on volume, which the old split made impossible. Maintenance finds parts faster, which cuts equipment downtime. A new product, a new supplier or a new region feeds the same model, the same platform and the same pipeline.
On MRO spend of this size, a 1 to 2 percent gain in procurement is tens of millions a year. One trusted catalogue is the condition for that gain.
What had to move together
Fix the model and skip the tooling, and you get a taxonomy nobody fills in. Deploy AI without the model, and the output is fast and wrong. Select a platform without the data and the enrichment workflow, and you pay for a system that does not fit. The three moved together, with independent advice across the model, the selection and the AI, and that is what produced the shifts above.
The trade-off is the human check. A steward on every suggestion is slower than letting the model write the catalogue unattended. It is also why a buyer can use a classification figure above 95 percent. Another industrial buyer can copy the order: UNSPSC and the attribute templates, then the platform, then domain AI with a person on the output.
What MDM is is the system-of-record problem the regions were solving with Excel. How to select a PIM is the path from 15 platforms to 3, run on the client's own data. AI-ready product data is what the record needs before a model classifies it, which is why generic consumer models failed on a butterfly valve. Product data quality and governance is the steward step that sits on top of the AI, and the definition of a complete MRO record the group did not have.
Diagnostic
Do you actually need a PIM?
Run the complexity index before you budget software or hire an SI.
Budget
Model a first-pass TCO
Translate catalog shape into a three-year cost range in under ten minutes.