Signal
Bluestone Webinar: Write Product Data for Agents Too
Nathalie · 2026-05-22 · Updated 2026-10-19 · 4 min read
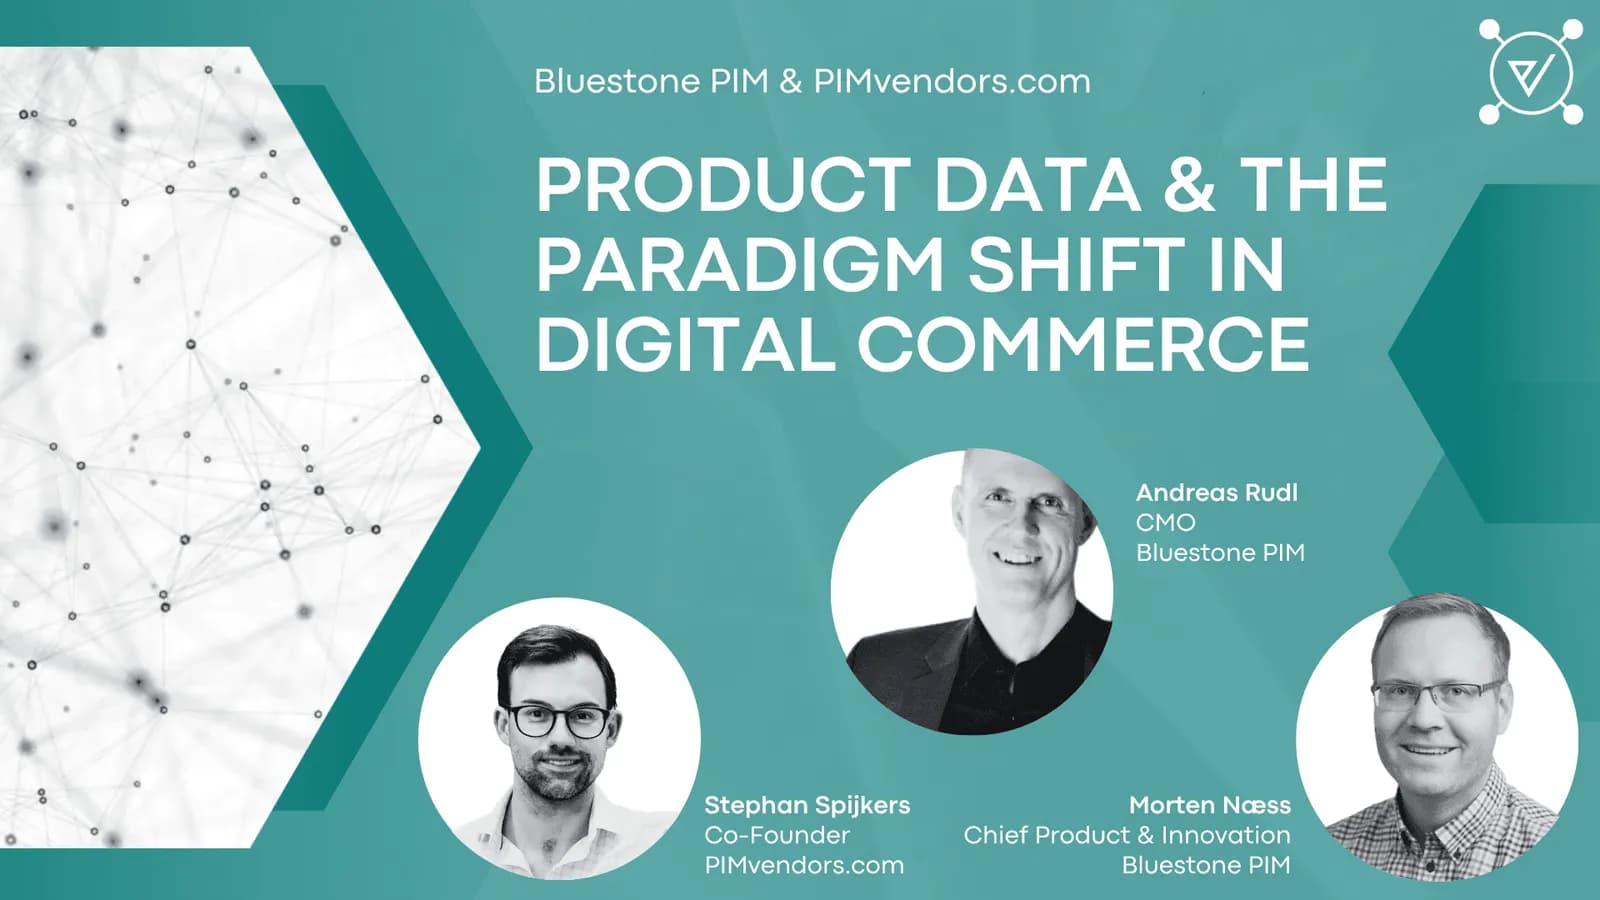
Product data written for a person who browses and compares fails when an agent does the comparing. That is the argument of this PIMvendors webinar with Bluestone PIM: Stephan Spijkers (Co-Founder, PIMvendors.com), Morten Næss (Chief Product & Innovation, Bluestone PIM) and Andreas Rudl (CMO, Bluestone PIM).
Most PIM systems were built for human shoppers. The session treats that design as already late. Direct human involvement in discovery is falling, contextual product data weighs more, and the architectural choices now separate teams that can feed agents from teams that will replatform inside the next two product cycles. That two-cycle line is the session's judgment, not a measured average.
AI-ready product data is the buyer-side version of the same problem: what the record has to contain before an agent can answer. The commerce stack guide shows where the PIM sits when several systems all claim the product.
Speakers
- Stephan Spijkers, Co-Founder, PIMvendors.com
- Morten Næss, Chief Product & Innovation, Bluestone PIM
- Andreas Rudl, CMO, Bluestone PIM
What the session argues
When agents compare, filter and buy, product content stops competing for attention and starts competing for selection. Structured attributes, machine-readable context and explicit relationships outrank persuasive copy. The session's claim is that teams still writing mainly for human eyes are already losing share in the agent-mediated path, even when current analytics do not show it. Treat that as their reading of the market, not as a published share figure.
Quality sets the ceiling. A capable agent does not repair incomplete attributes, missing relationships or stale records. It surfaces those gaps faster, and at a larger scale, than a merchandiser did. Putting agent features in before the record is fixed is, in their account, the usual reason commerce AI pilots stall before production. Product data quality and governance is where that fix actually starts: ownership, rules and a definition of complete.
Context does the discovery work that a flat attribute list cannot. Agents resolve intent by combining attributes with use cases, compatibility, regulatory requirements, regional availability and adjacent products. A complete list of fields, with no relationships, still leaves the agent guessing. The next layer of PIM value, as they frame it, is keeping that context on purpose, as part of the record.
Architecture follows. Legacy PIM, in the session, was a central repository with output channels tied tightly to it. Agent-led commerce wants the opposite: governed product data exposed through APIs to any number of agents, channels and downstream systems. Teams that hold a monolithic implementation, they argue, face replatforming cost within the next two to three product cycles.
The role they describe is shifting from "the system that stores product data" to the system that governs how product data is composed, checked and delivered to the agents acting for buyers. That changes the budget conversation, who owns the system, and what you put in a vendor shortlist. A board that still budgets PIM as a back-office tool is budgeting for a different system than the one this session is describing. What PXM stands for draws the same line from the other side: the experience sits on the record, and the record comes first.
The org chart is part of the same shift. Teams split by channel (web, marketplace, print) do not map onto one governed layer that feeds many agents. The session is direct: bolt AI onto the current org chart and the gains stay small. Restructure around the governed record and the agent workflows, and productivity and consistency move together. The trade-off is organisational. Channel teams lose the habit of keeping their own version of the product.
What to do with this
The closing call is for CTOs, and the clock they put on it is 18 to 24 months: the time they say it takes to replicate a head start in headless PIM, a product memory layer and agent-ready governance. Again, that is the session's range.
Their working advice is to set a PIM strategy now, treat it as something you revise, and budget for ongoing architecture work instead of a one-time implementation. The condition under which that advice changes is simple. If your channels are still almost entirely human, and you have no agent traffic to serve, the expensive move is replatforming early. The cheap move that still pays off is the record: complete attributes, relationships, and a named owner, so you are not starting from a blank catalog when the agent traffic arrives.
Diagnostic
Do you actually need a PIM?
Run the complexity index before you budget software or hire an SI.
Budget
Model a first-pass TCO
Translate catalog shape into a three-year cost range in under ten minutes.